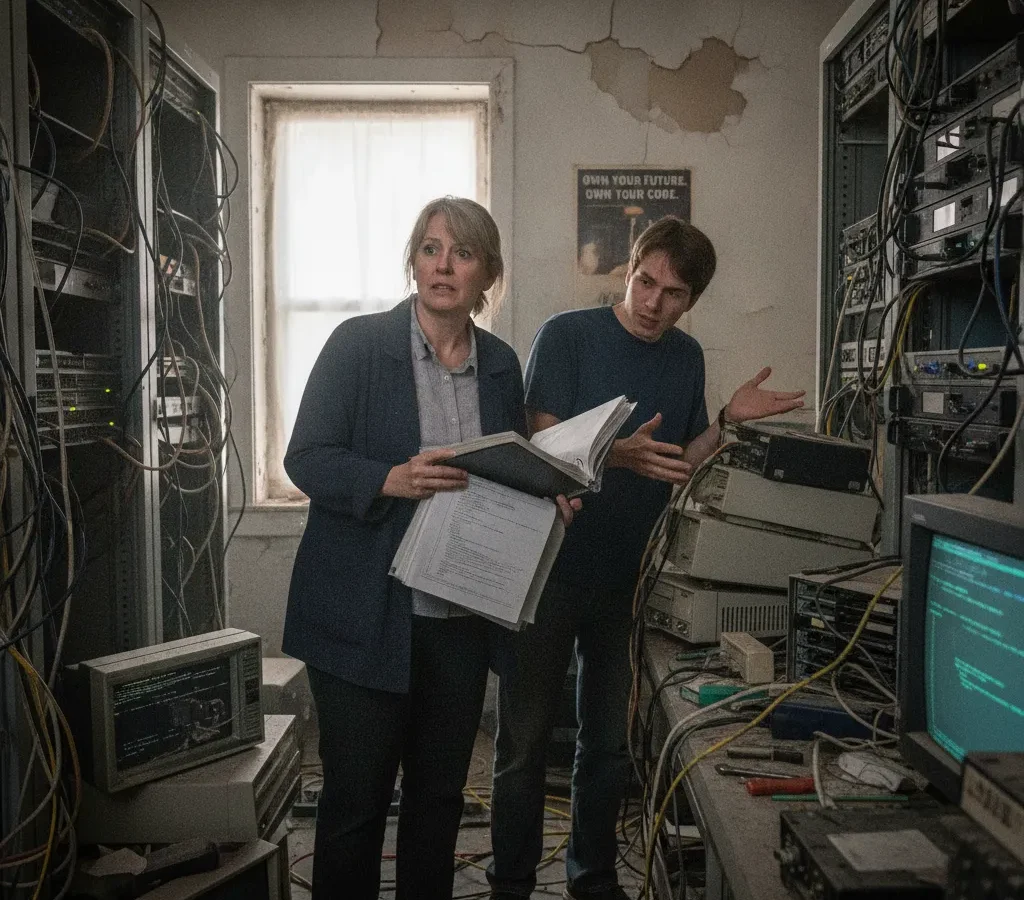
For decades, the tech industry operated on a comforting premise: if you owned the source code, you owned the system. Programming was designed for two audiences, the machine that ran the instructions and the human engineer who had to maintain them. This duality ensured that even the messiest legacy systems remained recoverable assets. If a lead developer quit or a vendor vanished, another skilled person could eventually sift through the lines of code, decode the logic, and regain control. Ownership was synonymous with human comprehension.
However, the rise of AI-generated software is quietly dismantling this foundation. While much of the conversation focuses on how AI makes developers faster, a more profound shift is occurring in how software is structured. We are entering an era where large portions of a system may be written, modified, and explained exclusively by AI. In this new landscape, the source code still exists in a repository, but it is no longer the primary vessel of understanding. Instead, the bridge between raw code and actual functionality runs through a language model.
This creates a precarious situation known as cognitive lock-in. A company may legally hold the copyright to its software while remaining functionally dependent on an external AI tool to interpret it. If that model provider changes their pricing, degrades their performance, or goes out of business, the company is left with a working system that no human knows how to fix or extend safely. Legal ownership becomes a hollow victory when the intellectual map required to navigate your own product lives on someone else’s server.
As these complexities mount, businesses will likely face a strange new form of technical debt. Unlike traditional messy code which is obvious to any auditor, AI-driven debt often hides behind a veneer of polish and perfect indentation. Systems may appear clean and efficient while lacking any internal human rationale for why they were built that way. To survive this transition, organizations will need more than just data backups; they will need continuity plans specifically designed to ensure that their institutional knowledge does not evaporate along with their API keys.